Speech Data Collection Tools Compared: Common Voice Has Just 16 Validated Hours of Hindi
Common Voice holds 29,295 validated hours, but only 16 in Hindi. We compare Common Voice, Karya, Appen, Defined.ai and web forms for collecting speech data.
The short version
- Open data runs thin outside big languages: Common Voice v27 (September 2026) holds 29,295 validated hours across 295 languages, but only 15.7 of them are Hindi and 0.9 are Telugu.
- Validation, not recording, is the bottleneck in volunteer projects. Common Voice has 1,278 recorded hours of Bengali and 54 validated, about 4%.
- Serious Indian-language collection is a field operation: IndicVoices gathered 7,348 hours from 16,237 speakers with 1,893 people involved, using the open-source Karya app.
- A web form with a voice field is the cheapest way to run your own scripted collection, if you supply the speakers, the consent process and the QC yourself.
Common Voice, the largest public-domain speech corpus, holds 29,295 validated hours across 295 languages. Only 15.7 of those hours are Hindi. If you need speech data for AI training in an Indian language, the open data will not carry you, and you will end up choosing a speech data collection tool to gather your own.
The hard part is not recording. It is finding speakers, proving consent and checking every clip. We read the release notes, the papers and the vendors' own pages, and compared five ways to collect an audio dataset on the jobs that actually decide the outcome.
The best speech data collection tool depends on who supplies the speakers. Use Mozilla Common Voice for free open data. Use a field partner such as Karya for thousands of rural speakers. Use a vendor such as Appen or Defined.ai for a contracted dataset. Use a web form with a voice field when you already have speakers.
What a speech data collection tool has to do
A speech dataset is pairs of audio and text, plus who spoke and under what terms. A tool that only records audio does a fifth of the job. The rest is recruiting speakers, recording consent, logging demographics and checking that each clip says what the text says.
We judge every option below on five questions. Who records? How is consent captured? Which languages are realistic? Who checks quality? And how do you pay? A tool that answers three of these well and two badly can still be the right choice, as long as you know which two.
Scripted speech and spontaneous speech need different tools
Scripted speech means a speaker reads a sentence you wrote. The transcript exists before the audio, so checking is a yes or no question: did they say it? Spontaneous speech means a speaker answers a prompt in their own words. Somebody then has to transcribe it, which costs far more.
Most tools handle scripted reading well. Spontaneous speech is where field operations and vendors earn their fees. We cover the method side of this choice in how to build a speech dataset for ASR.
Speech data collection tools at a glance
All vendor facts below come from each company's own pages as of October 2026. Where a page did not state something, we say so instead of guessing.
| Option | Who records | Consent | Languages | Quality control | Cost model |
|---|---|---|---|---|---|
| Mozilla Common Voice | Anonymous volunteers on the web | Contributors donate; data released as CC0 | 295 in Scripted Speech v27.0 | 2 listener votes per clip | Free to use; you cannot direct what gets recorded |
| Karya | Paid workers via its app, often rural | Not stated on its homepage | Says it covers 22 official Indian languages | Validation then transcription, per its case study | Custom project, pricing not published |
| Appen | Its contributor crowd, or a licensed dataset | "Explicit contributor consent with documented provenance" | Cites "500+ global locales" | Agreement metrics with adjudication | Quote on modality, locale and volume |
| Defined.ai | Its contributor network, or a licensed dataset | States every dataset is "fully consented" | Cites "500+" languages and locales | "Multi-layer validation" with automated checks and human review | Quote; no public price |
| Google Forms file upload | Your own speakers, using another recorder app | Your own consent question | Any | You listen to every file | Free, but slow per clip |
| Would You Rather voice form | Your own speakers, in the phone browser | Your own consent question | Any; transliteration help for Indian scripts | You listen; no built-in voting | Free to start |
The table hides one asymmetry. The first four bring speakers. The last two assume you already have them. That single question, whether you need people or only a tool, settles most decisions before price comes up.
Mozilla Common Voice: the open baseline
Common Voice is a volunteer project. Per the Common Voice paper, contributors record by reading sentences shown on screen, and other contributors vote on each clip. A clip that first gets two up-votes is marked valid; two down-votes mark it invalid. The corpus is released under CC0, so you can train commercial models on it.
That makes it the first place to look and the cheapest data you will ever get. It also means you get what volunteers chose to record, not what your model needs. You cannot ask Common Voice for 200 speakers from rural Bihar reading banking commands.
Validation is the bottleneck, not recording
The release statistics in the cv-dataset repository show the gap between audio recorded and audio checked. For Indian languages, the gap is wide.
- Recorded
- Validated
Across all languages, about 69% of recorded hours are validated. For Bengali it is about 4%. We think this is the most useful number in the whole comparison. Any crowdsourced project lives or dies on the second listener, and you should budget for listening time before recording time.
Bhasha Daan, the government volunteer channel
India's Bhashini mission runs a similar volunteer scheme called Bhasha Daan. A 2022 government factsheet describes its Bolo India strand as donating your voice by recording sentences and validating others' recordings. Contributions can be anonymous. The factsheet is from August 2022, so treat it as a description of the model, not of current volumes.
Karya and the field-collection model
Karya started as an open-source crowdsourcing platform from Microsoft Research and now runs as a data company. Its homepage describes "large-scale conversational datasets across 22 official Indian languages" and custom data work. It does not publish prices or pay rates.
Press reporting fills part of the gap. A 2023 Thomson Reuters Foundation report said Karya pays workers about $5 an hour and that workers own part of the data they generate. That is the company's own claim as reported, and it is three years old.
What IndicVoices shows about scale
The best public account of Indian field collection is the IndicVoices paper from AI4Bharat and IIT Madras. The team used the open-source Karya Android app because it works offline and syncs later. That matters in districts with patchy connectivity.
The numbers show what "field operation" means. IndicVoices collected 7,348 hours from 16,237 speakers in 145 districts, with 1,893 people working on it. Each district had 1 to 2 local mobilisers and 5 to 7 coordinators. A coordinator sat with each participant, checked every response on the spot and asked for repeats.
Even then, the paper reports problems a tool cannot fix. Some registration forms carried false age or gender to meet quotas. Some participant IDs had several different voices behind them. The team added a short identity video, reviewed only by female QC staff and deleted after checking. We would not try to reach this scale without a partner that already has people on the ground.
Data vendors: Appen and Defined.ai
If you need a contract, a delivery date and someone else's legal team, a vendor is the honest answer. Both companies offer two things: licences for datasets they already hold, and custom collection.
Appen's datasets page lists 597 off-the-shelf datasets across nine categories and cites "500+ global locales". It says custom collection suits projects needing "specific demographics, acoustic environments, specialist domains, or a controlled collection protocol". On consent, it states that all data is collected "under explicit contributor consent with documented provenance". Pricing is by quote.
Defined.ai's data collection page cites 1.6M+ contributors in 150+ countries and 500+ languages. It states that every dataset is "fully consented, copyright-cleared, and privacy-compliant". For audio it lists conversational dialogues, IVR interactions and studio recordings. It does not publish a price model.
Where vendors are the better choice
Vendors win when your speakers are hard to find and you have budget but no time. They also win when procurement needs a named counterparty for consent and provenance. A web form cannot recruit 500 native Somali speakers for you. That is the honest limit of the DIY options below.
Collecting speech data yourself with a web form
The DIY route fits a different situation. You already have speakers: your own users, a partner NGO's field staff, students, or a panel you recruit. You need them to read a script and send clean clips, and you need it this week.
Google Forms needs a separate recorder
Google Forms has no voice question. Google's help page lists file upload as the closest type, and states that responders must sign in to a Google Account to answer it. So each speaker records in another app, finds the file, and uploads it. For a 50-sentence script, that is 50 round trips. We go through the workarounds in whether Google Forms can record audio.
A voice form records in the phone browser
Would You Rather is our product, so read this section with that in mind. Each script sentence becomes one voice question. The speaker sees one sentence at a time, taps record, listens back, re-records if needed and moves on. No app install, and anonymous answers are a per-form setting.
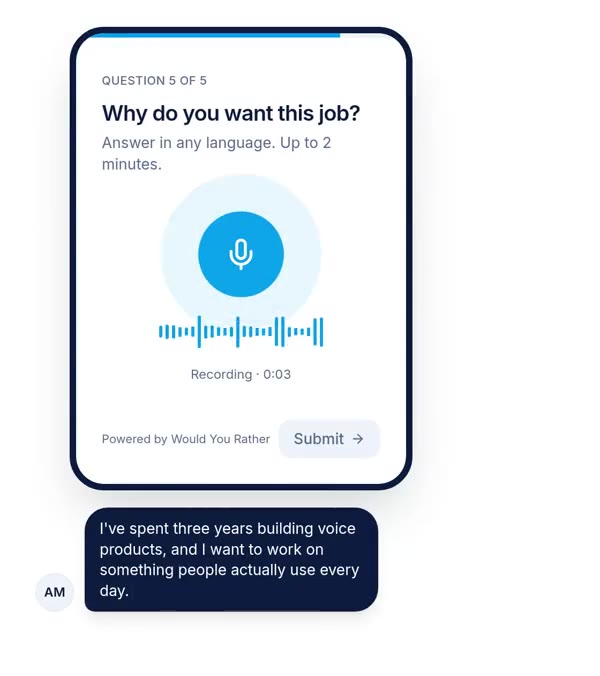
For script-reading projects we can switch on a transcript mode. The script sentence is prefilled as an editable transcript under the recorder, and the speaker corrects it only if they said something different. Typing in English letters offers suggestions in the target Indian script. Each voice question also takes a minimum and a maximum length, so a 1-second accidental tap is rejected. Transcript mode is not yet a switch in the builder, so ask us to set it up.
Recordings land next to the speaker's other answers, with audio links in a live Google Sheet or CSV. What it does not do matters as much. There is no built-in second-listener vote, no auto-transcription and no speaker pool. You bring the people and the QC. We cover the general recording flow in collecting voice recordings online.
How to choose a speech data collection tool
Decide in this order. Each step removes options, and most teams are down to one before they reach step 4.
- 1Check the open corpora firstDownload the Common Voice release for your language and count validated hours, speakers and gender split. If it covers you, stop here.
- 2Decide whether you need speakers or only a toolIf you have no access to your target speakers, you need a field partner or a vendor. A form cannot recruit.
- 3Decide between scripted and spontaneous speechScripted reading is cheap to check. Spontaneous speech needs transcription, which usually means a vendor or a transcription team.
- 4Write the consent text before the first recordingState the purpose, who can use the data, whether it will be published and the payment. Record agreement per speaker.
- 5Run a 10-speaker pilotListen to every clip. Count rejects by reason. Fix the script and instructions before you scale.
- 6Scale only what passed the pilotKeep the second listener in the loop at scale. Budget listening hours, not just recording hours.
When another option beats a web form
| Situation | Better option | Why |
|---|---|---|
| You need free data today | Common Voice | Already validated, CC0, no recruitment |
| You need rural speakers you cannot reach | Karya or a similar field partner | Local coordinators, offline app, on-site checks |
| You need a contract and documented provenance | Appen or Defined.ai | Named counterparty, stated consent process |
| You have speakers and a script | A voice form | One link, phone browser, clips arrive per sentence |
Where this comparison is weakest
We did not run a paid project with any vendor, so we cannot compare their real turnaround or reject rates. Everything about Appen, Defined.ai and Karya comes from their own pages, plus one 2023 press report for Karya's pay. Vendor pages describe intent, not audited outcomes.
The Common Voice numbers are exact but narrow. They count hours, not quality. A validated hour from 3 speakers is worth far less for training than one from 300, and the headline totals hide that. Check speaker counts per language before you trust an hour figure.
IndicVoices is one project, run by a well-funded academic team. Its processes describe what worked for them, not a minimum. And our own product's section is written by us. The most important line in it is the list of things it does not do.
Where to start this week
Open the Common Voice release statistics for your language and write down three numbers: validated hours, speakers, and the share of female speakers. If any is too low, you have your case for collecting.
Then write 50 script sentences, put them in a voice form and send it to 10 speakers you already know. Listen to all 500 clips yourself. You will learn more about your script, your instructions and your reject reasons in that afternoon than from any vendor call. If your speakers write in Indian scripts, read collecting answers in Hindi, Tamil or any language first.
References
- Ardila, R. et al., Common Voice: A Massively-Multilingual Speech Corpus, LREC 2020. Used for the recording and validation process and the CC0 licence.
- Mozilla Common Voice, cv-dataset repository, release statistics for Scripted Speech v27.0, 11 September 2026. Used for total, validated and per-language hours.
- Javed, T. et al., IndicVoices: Towards building an Inclusive Multilingual Speech Dataset for Indian Languages, arXiv preprint, March 2024. Used for field collection scale, staffing, the Karya app and QC problems.
- Ministry of Electronics and IT, BHASHINI factsheet, Press Information Bureau, 26 August 2022. Used for the Bhasha Daan description.
- Karya, homepage, accessed 8 October 2026; and Thomson Reuters Foundation, Context, "India turns to AI to capture its 121 languages", 4 December 2023. Used for Karya's stated offering and reported pay.
- Appen, off-the-shelf datasets page, accessed 8 October 2026. Used for catalogue size, locales, consent statement and custom collection.
- Defined.ai, data collection page, accessed 8 October 2026. Used for contributor numbers, languages and consent statement.
- Google, Choose a type of question for your form, accessed 8 October 2026. Used for the file upload sign-in rule.
The weakest point in this source base: every vendor fact is self-reported marketing copy, and the only figure on Karya's pay comes from a 2023 press report of a company statement.
Questions people ask
What is the best tool to collect speech data for AI training?
It depends on who supplies the speakers. If you need open data, start with Mozilla Common Voice. If you need thousands of speakers in Indian villages, a field-collection partner such as Karya fits. If you need a contract and a deadline, a vendor such as Appen or Defined.ai will quote. If you already have speakers, a web form with a voice field is the cheapest way to collect scripted recordings yourself.
How do I crowdsource voice recordings?
Write short prompts, recruit speakers who match your target users, and give them a link that records audio in the browser or an app. Collect consent and basic demographics before the first recording. Then have a second person listen to every clip and mark it accept or reject. Common Voice uses exactly this pattern: one person records, and two listeners must agree before a clip counts as valid.
Is Mozilla Common Voice data free to use commercially?
Yes. The Common Voice paper states the corpus is released under a Creative Commons CC0 licence, which places it in the public domain. You can train commercial models on it. The catch is coverage, not licence. As of release 27.0 in September 2026, many Indian languages have only single-digit or low double-digit validated hours, which is too little to train a usable recogniser on its own.
How much speech data do you need to train an ASR model?
There is no single number, because it depends on whether you train from scratch or fine-tune a pretrained multilingual model. For scale reference, LibriSpeech offers about 1,000 hours of English, and IndicVoices targeted about 20,000 transcribed hours across 22 Indian languages. Fine-tuning projects often start far smaller. Run a pilot, measure word error rate on a held-out speaker set, and add data where errors cluster.
Can I collect speech data with Google Forms?
Only as a workaround. Google Forms has no audio question type. Respondents must record in another app and upload the file through a file upload question, and Google's help page states that responders must sign in to a Google Account to answer one. That adds two steps per clip, which is painful for a script of 50 sentences. A form builder with a native voice field records in the browser instead.
Drafted with AI from published research, then edited and approved by Shivam Singh.
Would you rather hear the answer?
Make a voice form in a minute. It’s free.
Create a form